Fable 5.2 vs. the field: five real jobs, one winner?
We gave Claude Fable 5.2, Claude Opus 5.5 and GPT-6 Astra the same shift at a fictional campus theater. Then we checked their work.
Two bookings, one room, seven o'clock. In our test calendar, somebody had entered the same show twice. When we ran each model's instructions to move the show back half an hour, Fable and Astra moved both bookings to 7:30. Opus had written an extra check. It left the two records in place for a human to sort out.
Fable was getting the attention. The Aigentic's Watch tally counted seven channels covering it in a 24-hour span. Our count of X posts mentioning "Fable 5.2" rose from single digits a day to about 28,500 on November 10 and about 43,000 partway through November 11. Closing Time covered Anthropic's launch on November 9. We wanted to know which jobs justified the price.
Closing Time, Nov. 9 · The Aigentic Watch
Where Peter Yang saw a difference
Peter Yang preferred Fable on four of five jobs, including a 3D kart racer and a website redesign. His writing test was blind. He picked Fable's essay in four of five comparisons. Opus won when he pushed the models to agree with him. If you only watch one section, start with the essays at 11:33.
Essay comparison at 11:33 · Yang's recap at 19:48
Five jobs, three models, two passes each
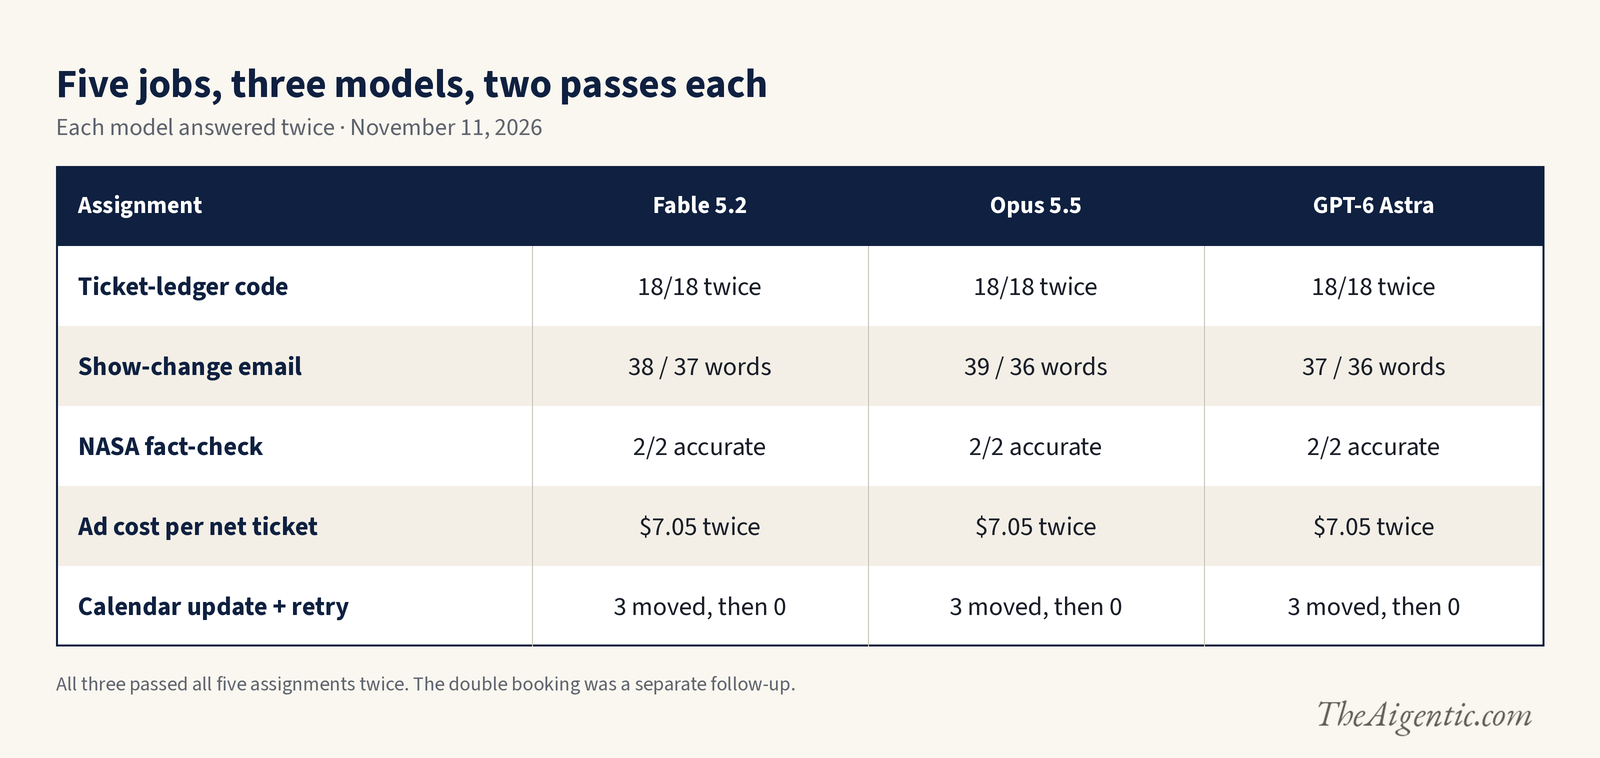
We sent the same five-part brief through Cleus in three live pairings, rotating each model between the two positions. Each model answered twice. The service caps replies at about 250 words and reports elapsed time. Reasoning settings and token counts were unavailable. We ran the returned Python and SQL and checked the prose and arithmetic against the brief.
Cleus comparison tool · Reading Astra's launch benches
| Assignment | Fable 5.2 | Opus 5.5 | GPT-6 Astra |
|---|---|---|---|
| Ticket-ledger code | 18/18 twice | 18/18 twice | 18/18 twice |
| Show-change email | 38 / 37 words | 39 / 36 words | 37 / 36 words |
| NASA fact-check | 2/2 accurate | 2/2 accurate | 2/2 accurate |
| Ad cost per net ticket | $7.05 twice | $7.05 twice | $7.05 twice |
| Calendar update + retry | 3 moved, then 0 | 3 moved, then 0 | 3 moved, then 0 |
Tap to enlarge.
All three passed all five assignments twice. The double booking was a separate follow-up.
What happened on each job
1. Close the ticket ledger
A payment service sometimes delivers a transaction twice. The Python function had to count an exact replay once, subtract refunds and flag two conflicting entries with the same ID. An entry after closing time had to be ignored, even if it looked like a conflict. All six functions passed 18 checks apiece, including six different arrival orders for the same three transactions.
2. Write the notice ticket holders need
Friday's show had moved from 7 to 7:30 p.m. Doors still opened at 6:15, existing tickets were good, and anyone who wanted a refund had to email the box office by noon Friday. The brief allowed 35 to 45 words. All six emails fit and preserved every detail. Fable's "Prefer a refund?" was a nice edit. It would be a thin reason to double the writing budget.
3. Fact-check an asteroid story
An editor had confused a change in orbital period with a change in distance from Earth. We supplied two NASA source summaries. Every answer identified Dimorphos as the body orbiting Didymos and reconciled the estimates. NASA's later figure of 33 minutes 15 seconds fell inside the initial range of 30 to 34 minutes. This tested how well each model read the supplied evidence.
NASA's 2022 measurement · NASA's 2024 study
4. Work out what a ticket actually cost
One advertising channel spent $60, sold four tickets and refunded all four. Another channel's $360 entry appeared twice. Every model counted that entry once, kept the $60 in total spending and called the first channel's cost per net ticket undefined. Across the campaign, $620 bought 88 net tickets, or $7.05 each. Dropping the channel that sold nothing net would have made the campaign look cheaper at $6.36.
5. Give the assistant the calendar
Each model could issue one database update. We executed the SQL inside each proposed call on a fresh copy of a 12-record calendar. Three holds qualified to move. All six updates moved those three, left an occupied room alone and changed zero rows on a retry.
Then we added the two 7 p.m. holds in one room and executed the same statements again on fresh copies. Both Opus answers had included a count of bookings at the old time. Both left the collision at 7. Every Fable and Astra answer carried it to 7:30. None of the models had seen those records, and we had given them no rule for that case.
The test kit includes the original prompt, all six model replies and the scoring code.
Where Fable earns its premium
Finding a bug somewhere in a large codebase is a different job from writing a function whose rules fit in four sentences. Anthropic reports that Fable solved 69.9% of FrontierSWE v2, against 65.5% for Astra and 62.3% for Opus. An independent test gives that gap a price tag.
Fixing 105 bugs across two codebases
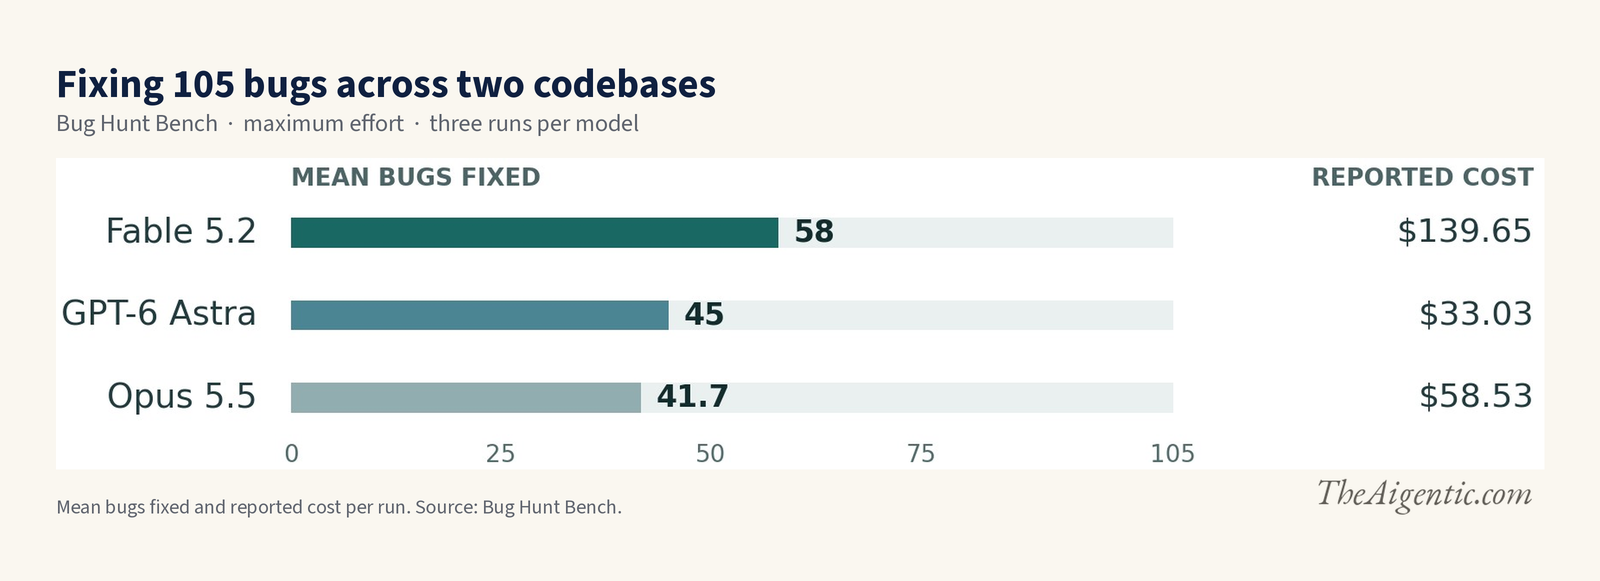
On Bug Hunt Bench, Fable fixed 13 more bugs on average than Astra. The benchmark's reported cost was about $107 higher per run. If you're chasing a release-blocking defect, that extra reach can be worth buying. Astra fixed 45 bugs at about $33, the lowest reported run cost of the three. The benchmark used each vendor's own coding tool and graded the patches blind.
Bug Hunt Bench results and method
What to pay for this week
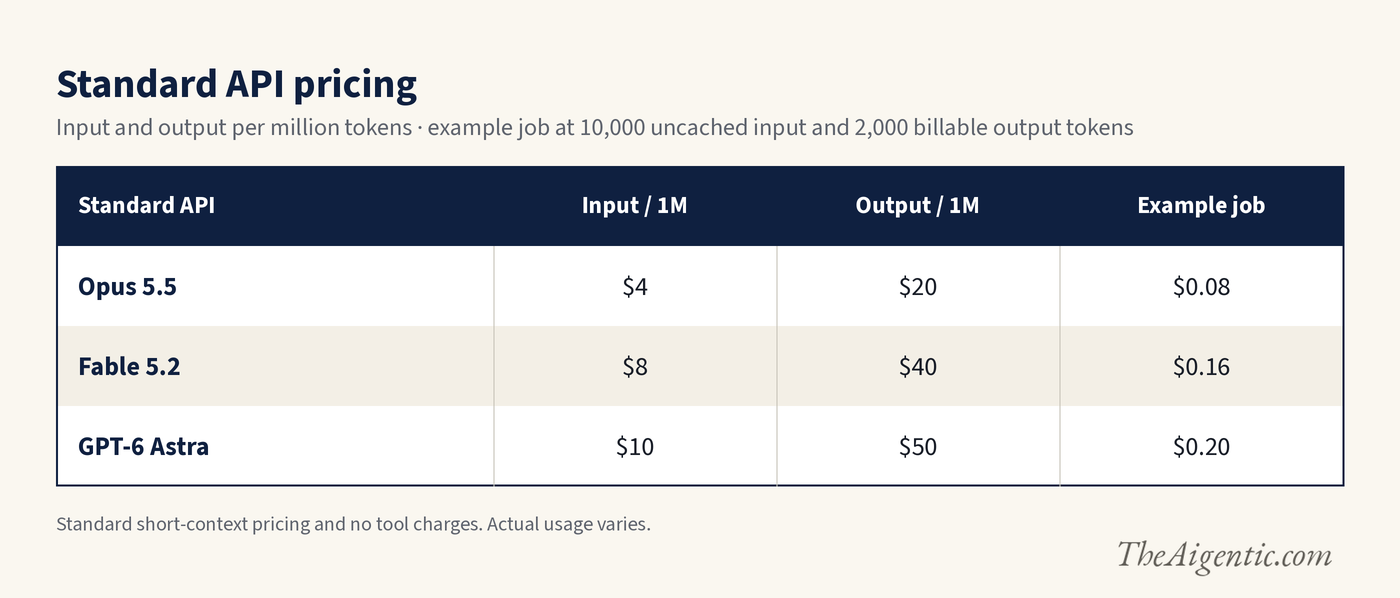
Opus is our pick for the everyday work we tested. It met every brief, handled the double booking conservatively and costs half as much per token as Fable. Astra returned our full brief in 10.1 and 11.3 seconds. The four Claude replies took 14.1 to 17.0 seconds. That's a reason to try Astra on a deadline, with two timings per model as a starting point.
| Standard API | Input / 1M | Output / 1M | Example job |
|---|---|---|---|
| Opus 5.5 | $4 | $20 | $0.08 |
| Fable 5.2 | $8 | $40 | $0.16 |
| GPT-6 Astra | $10 | $50 | $0.20 |
Tap to enlarge.
Example assumes 10,000 uncached input tokens and 2,000 billable output tokens, standard short-context pricing and no tool charges. Actual usage varies.
Claude API pricing · OpenAI's Astra pricing
If you already use Claude Pro or a standard Team seat, try Fable on the hardest job in your backlog before buying extra usage. Through November 16 at 11:59 p.m. Pacific, the launch offer lets Fable use up to half your weekly allowance. A stubborn migration or a visual prototype you can judge side by side is a better use of that trial than another box-office email.